AI products fail for a surprising reason: not because the model is wrong, but because people can’t tell when it’s wrong. The defining design challenge of this era isn’t capability. It’s calibrated trust.
Calibrated means people trust the system exactly as much as it deserves: they rely on it where it’s strong and check it where it’s weak. Too little trust and nobody uses the feature. Too much, and the first confident mistake does real damage.
1. Make the system legible
People extend trust to systems they can predict. That means showing your work: surfacing confidence, citing sources, and making it obvious when the AI is reasoning and when it is retrieving.
- Show the inputs the model used to reach an answer.
- Separate generated content from verified content, visually.
- Give people a graceful path to correct or override.
Legibility is also about what you leave out. A wall of citations is as unreadable as none at all. Show the one source that decided the answer, and let people open the rest if they want to check.
2. Design for recovery, not just success
The happy path is the easy part. Great AI experiences are defined by how they handle ambiguity, low confidence and outright failure. Build the “I’m not sure” state with the same care as the answer.
3. Keep humans in the loop where it matters
Automation should compress effort, not remove judgment. The best AI copilots make people faster and more confident. They never quietly make irreversible decisions.
The useful question isn’t “should a person approve this?” but “what happens if this is wrong?” If the answer is a typo in a draft, let the AI act and make undo easy. If the answer is a price sent to a client or a record deleted, stop and ask. Draw that line explicitly, per action, instead of hoping one global setting fits everything.
Trust isn’t a feature you add at the end. It’s the architecture.
4. Measure trust, not just usage
Usage tells you people opened the feature. It doesn’t tell you whether they believed it. The signals I look at instead:
- How often people edit or override a suggestion before accepting it.
- How often they open the source before deciding.
- Whether they come back to the feature for the decisions that matter, or only for the easy ones.
Calibration cuts both ways. A rising override rate on something people used to accept is an early warning that quality slipped. But a feature that is accepted every time without a single check can be a warning too: people may be trusting it more than it deserves.
In practice: how Cohivo handles money
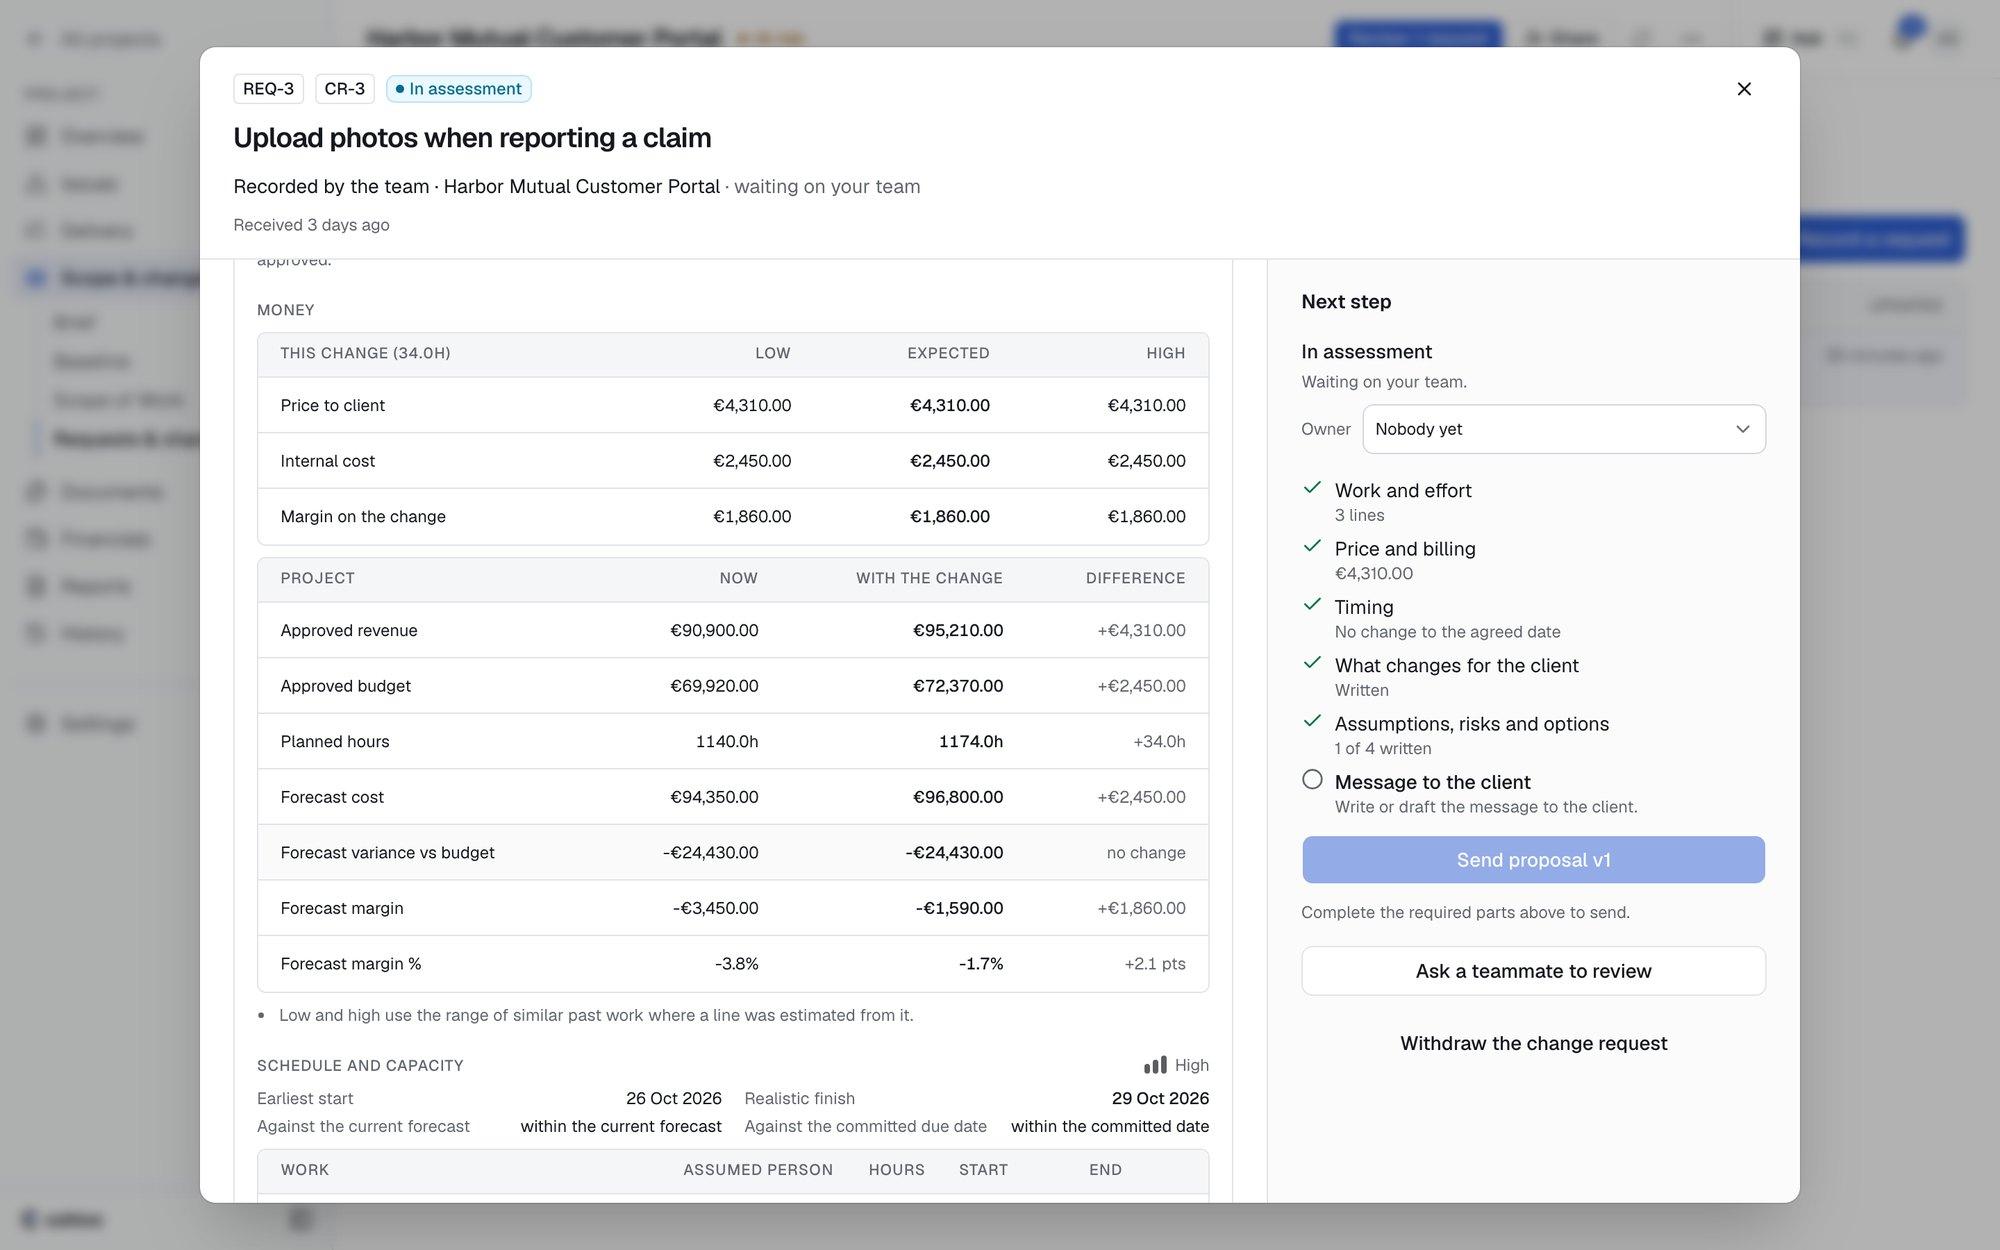
In Cohivo, my scope-control product for agencies, all of these ideas became one hard rule: prices, hours and dates never come from the language model. They come from the agency’s rate card through deterministic rules. The AI drafts the wording and cites the clause it used, and nothing reaches the client until a person on the team approves it.
Every verdict links to the clause, task, time entry or message behind it, with a stated confidence. And a redaction gate means internal cost, rates and margin can’t reach the client portal at all. Trust there isn’t a promise in the interface copy. It’s enforced by how the product is built.